Search and Read the Web
Open in CMSYour agent answers questions from the knowledge base you give it. But sometimes the information a user needs is not in your documents. It lives on the open internet, or on a website that changes often. The Web Search and Web Scraping features let your agent reach beyond its knowledge base and read live content from the web during a conversation.
In this tutorial you set up both features for Atlas, Kirana Group's operations assistant. Kirana's site supervisors and safety staff often ask about public safety guidance, for example from the UK Health and Safety Executive (HSE). Kirana's SOPs do not cover every detail, and the official guidance changes over time. So you let Atlas search the web, but only on official sources: hse.gov.uk and ilo.org.
What Is Web Search?
Web Search lets your agent run a real-time internet search during a conversation. When a user asks something the agent cannot answer from its knowledge base, the agent sends a query to a search engine, gets a ranked list of results, and uses them to write a grounded, up-to-date answer. All of this happens in the same chat turn.
Think of it as a search engine the agent consults on its own, without the user leaving the conversation.
When to use Web Search
- Your agent needs to answer questions about things that change over time, such as public regulations, guidance, or prices
- You want to reduce the work of keeping your knowledge base up to date
- Your agent handles a broad set of topics and you cannot anticipate every question
What Is Web Scraping?
Web Scraping goes one step further. Instead of a list of search-result snippets, it fetches the full content of a specific web page and converts it into clean, readable markdown. The agent then uses that content to answer the user's question in detail.
This is useful when a user shares a URL, or when the agent needs to read an actual page (a guidance page, a news article, a documentation page) rather than just know that the page exists.
When to use Web Scraping
- Users share URLs and expect the agent to summarize or answer questions about that page
- You want the agent to read the full text of a page, not just a search-result excerpt
- Your agent needs to process structured pages like documentation, specifications, or guidance pages
How the Two Features Compare
| Web Search | Web Scraping | |
|---|---|---|
| What it retrieves | A ranked list of result snippets from a search engine | The full text content of a specific web page |
| Triggered by | A question the agent cannot answer from its knowledge base | A URL shared in conversation, or a need for full-page content |
| Output format | Search result summaries | Markdown-formatted page content |
| Domain restriction | Allow up to 20 domains | Ignore specific paths or file types |
| Image handling | Not applicable | Configurable size filters |
| Best for | Real-time factual queries | Deep reading of a specific page |
Both features can be on at the same time, and they complement each other.
Web Search or a Website in Knowledge? In Websites you index one HSE page into Atlas's knowledge base ahead of time. That is the right choice for a page you know users will need. Web Search covers the questions you did not anticipate, and always reads the current version of the source.
Benefits
Web Search benefits
- Always up to date: the agent finds the latest information without manual knowledge base updates
- Broader coverage: it handles questions outside the scope of your curated documents
- Source transparency: answers can name and link the pages the information came from
- Domain filtering: you can restrict searches to trusted domains only, so answers stay reliable
Web Scraping benefits
- Full-content understanding: the agent reads the actual page, not just a summary
- URL-aware conversations: users can paste a link and immediately ask the agent to explain or summarize it
- Markdown precision: content is extracted as clean structured text, with less noise from ads and navigation
- Image control: you can include or exclude images and filter them by file size
Risks and Considerations
Note: Both features make outbound requests to external websites during conversations. Understand what that means before you turn them on for real users.
Web Search risks
| Risk | Description |
|---|---|
| Inaccurate sources | Search results may include pages with wrong or outdated information. Reduce this by allowing only trusted domains. |
| Off-topic results | Without a domain list, the agent may draw on content that has nothing to do with your use case. |
| Latency | Each search adds a network round trip to the response time. Keep Max Web Search Results low and choose a shallower Search Depth to reduce it. |
| Data leakage | The user's query is sent to a search engine. Avoid turning on Web Search for agents that handle confidential or personal information. |
Web Scraping risks
| Risk | Description |
|---|---|
| Terms of service | Some websites prohibit automated scraping. Make sure the sites your agent reads permit it. |
| Dynamic content | Pages built entirely with JavaScript may not render within the configured timeout. |
| Excessive payload | Large pages with many images can slow down responses. Use the image size filters and the ignored paths to control what gets fetched. |
| Sensitive content exposure | If a user gives a URL to an internal or sensitive page, the agent tries to read it. Consider your audience before you turn this on. |
Before you start
- You have an agent. If not, follow Create Your First Agent first.
- Your agent already answers well from its own sources. Finish Teach Your Agent first, so the web fills gaps instead of replacing your knowledge base. For Atlas, that means SOP-FIN-007 and the HSE ladders page are already in Knowledge.
- You know how to test and publish changes. See Preview and Publish Changes.
- You are signed in as an Owner or Contributor of the agent. Viewers cannot open these settings.
- You have opened the agent (Atlas) from the agent list, so it is the active agent.
Part 1: Configure Web Search
Step 1: Open the Web Search page
In the left sidebar, expand Tools and click Web Search.
The page has two sections: Web Search Configuration and Domain Whitelist.
Step 2: Turn on Web Search and choose how much it searches
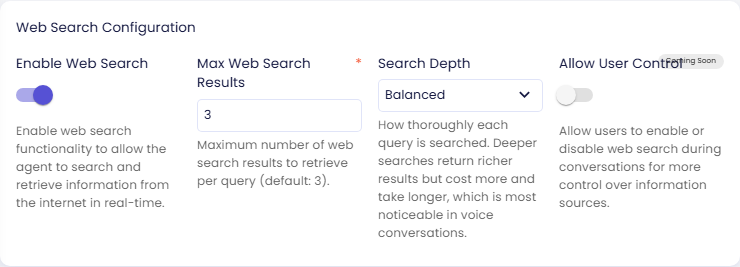
In Web Search Configuration, set the controls like this for Atlas:
| Control | Value for Atlas | What it does |
|---|---|---|
| Enable Web Search | On | Lets the agent search and retrieve information from the internet in real time. It is off by default. |
| Max Web Search Results (required) | 3 | How many search results the agent retrieves per query. The default is 3. |
| Search Depth | Balanced | How thoroughly each query is searched. |
| Allow User Control | Off (marked Coming Soon) | Will let users turn web search on or off during a conversation. It cannot be turned on yet. |
Max Web Search Results trades speed for context:
| Value | Effect |
|---|---|
1 | Fastest responses, but limited context for the agent |
3 (default) | A good balance of speed and answer quality |
| Higher values | Richer context, but slower responses because more data is fetched |
For most agents, keep it between 3 and 5.
Search Depth decides how hard the search looks. Max Web Search Results decides how many pages come back; Search Depth decides how thoroughly each query is worked.
| Depth | Effect |
|---|---|
| Fast | Lowest latency and cost. Best for agents that search often, and for voice conversations, where a pause is much more noticeable than in chat |
| Balanced (default) | The search picks its own strategy per query. A sensible starting point for most agents |
| Deep | The most thorough and the most expensive. Suited to research-style agents, where completeness matters more than speed |
Deeper searches cost more per query, and the cost is charged to your organization's credits. If your agent searches on most turns, start at Fast or Balanced and move to Deep only if answers really come up short.
Tip: To try the feature without affecting real users, test it in the preview before you publish. Your changes stay in draft until you click Publish.
Step 3: Allow only official domains
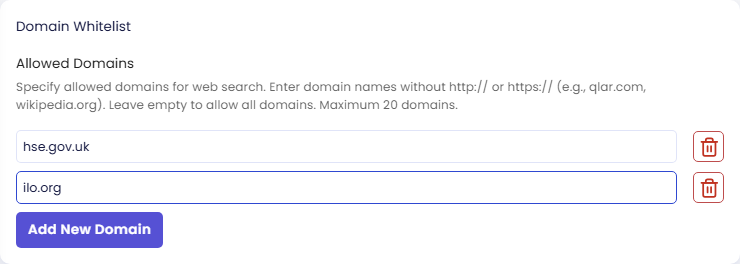
By default, Web Search queries the whole internet. For Atlas, safety answers must come from official sources, so you restrict the search in Domain Whitelist.
- Under Allowed Domains, click Add New Domain.
- Type
hse.gov.uk. - Click Add New Domain again and type
ilo.org.
Enter each domain without http:// or https://:
| ✅ Correct format | ❌ Incorrect format |
|---|---|
hse.gov.uk | https://www.hse.gov.uk/ |
ilo.org | http://ilo.org |
Domain names must contain at least one dot and use only letters, numbers, hyphens, underscores, and dots. You can add up to 20 domains. When the list has entries, the agent searches only those domains. Leave it empty to allow all domains.
To remove a domain, click the red delete icon to the right of it.
Tip: Start with two or three authoritative sources. You can add more later. A short, curated list greatly reduces the chance of the agent citing inaccurate or off-topic content.
Step 4: Save
Click Save at the bottom of the page. Your changes are saved as a draft: you can try them in the preview right away, and real users get them after you click Publish.
Part 2: Configure Web Scraping
Step 1: Open the Web Scraping page
In the left sidebar, still under Tools, click Web Scraping.
The page has three sections: Web Scraping Configuration, Image Size Filters, and Ignored Paths.
Step 2: Turn on Web Scraping
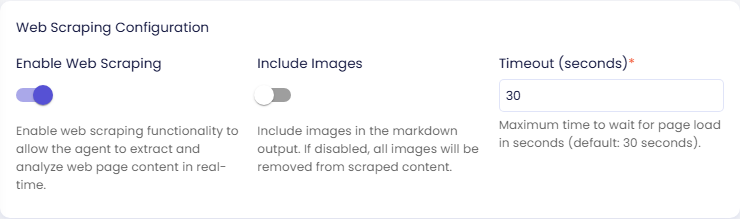
In Web Scraping Configuration, set the controls like this for Atlas:
| Control | Value for Atlas | What it does |
|---|---|---|
| Enable Web Scraping | On | Lets the agent extract and analyze web page content in real time. |
| Include Images | Off | When on, images are included in the markdown output. When off, all images are removed from scraped content. Atlas only needs the text of guidance pages. |
| Timeout (seconds) (required) | 30 | The maximum time to wait for a page to load. The default is 30 seconds. |
The timeout must be between 5 and 60 seconds:
| Scenario | Recommended value |
|---|---|
| Fast, text-heavy pages (documentation, guidance) | 15 to 20 |
| Standard pages | 30 (default) |
| Heavy pages with many resources | 45 to 60 |
A timeout that is too low causes partial or failed fetches on slower pages. One that is too high makes the agent wait longer when a page is unreachable.
Tip: If images do not matter for your use case, leave Include Images off. It is the most effective way to speed up web scraping.
Step 3: Check the image size filters
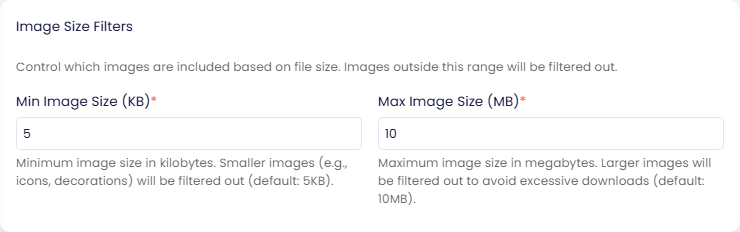
Image Size Filters decide which images are kept when Include Images is on. Images outside the range are filtered out. Atlas has images off, so leave the defaults:
- Min Image Size (KB) (required):
5. Smaller images, such as icons and decorations, are filtered out. - Max Image Size (MB) (required):
10. Larger images are filtered out to avoid excessive downloads.
| Setting | Min allowed | Max allowed | Default |
|---|---|---|---|
| Min Image Size | 1 KB | 10,240 KB (10 MB) | 5 KB |
| Max Image Size | 1 MB | 50 MB | 10 MB |
Step 4: Ignore paths you do not need
Ignored Paths lists patterns the scraper skips. Official safety sites link to many PDF leaflets, which are slow to fetch and not needed for a short answer. So for Atlas you skip PDF files:
- Under Path Patterns to Ignore, click Add New Path Pattern.
- Type
*.pdf.
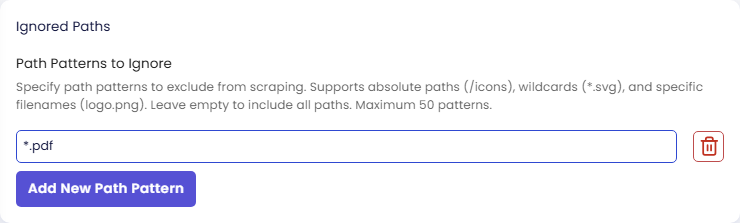
Each pattern can take one of these forms:
| Pattern type | Example | What it excludes |
|---|---|---|
| Absolute path | /icons | Everything under the /icons/ path |
| Wildcard by extension | *.svg | All SVG files, whatever the path |
| Specific filename | logo.png | Any file named logo.png |
You can add up to 50 patterns, each up to 200 characters. Leave the list empty to include all paths. To remove a pattern, click the delete icon to the right of it.
Tip: Common patterns to ignore:
*.svg,*.ico,*.woff,*.woff2,/cdn-cgi,/wp-content/uploads. These are usually assets the agent does not need to read.
Step 5: Confirm and save
Click Save at the bottom of the page.
Unlike Web Search, Web Scraping shows a confirmation dialog before it applies your settings. Review the summary and click Confirm. The extra step exists because these settings change how the agent processes external content, which affects answer quality and latency.
The new settings are saved as a draft. Real users get them after you click Publish.
Using Both Features Together
Web Search and Web Scraping work independently, but pair well:
- A user asks something the agent cannot answer from its knowledge base.
- Web Search finds the most relevant pages on the allowed domains.
- Web Scraping fetches the full content of the top result.
- The agent writes a detailed, sourced answer from the full page text.
Turning on both gives your agent the broadest access to live information, but each adds latency and an external dependency. Start with Web Search only, measure the effect on response times, and add Web Scraping when you need deeper reading.
Common Mistakes to Avoid
| Mistake | Why it matters | Fix |
|---|---|---|
| Leaving Allowed Domains empty in a business context | The agent may cite unreliable sources | Add a curated list of 2 to 5 trusted domains |
| Setting Max Web Search Results above 5 | Higher values add noticeable latency | Keep it at 3 to 5 unless depth is critical |
| Turning on Include Images without size filters | Large images slow down extraction | Set Max Image Size (MB) to 2 to 5 for typical use |
| Using a timeout below 10 seconds | A short timeout causes frequent scraping failures | Use 20 to 30 seconds as a baseline |
| Turning on Web Scraping for confidential conversations | Users can share any URL, including internal pages | Turn on scraping only when the audience and content are appropriate |
| Not testing after configuration | Settings may not work as expected on every site | Test with 3 to 5 representative questions or URLs before you publish |
Check the result
-
Open the preview panel on the right of the CMS and click the reload button to start a fresh conversation.
-
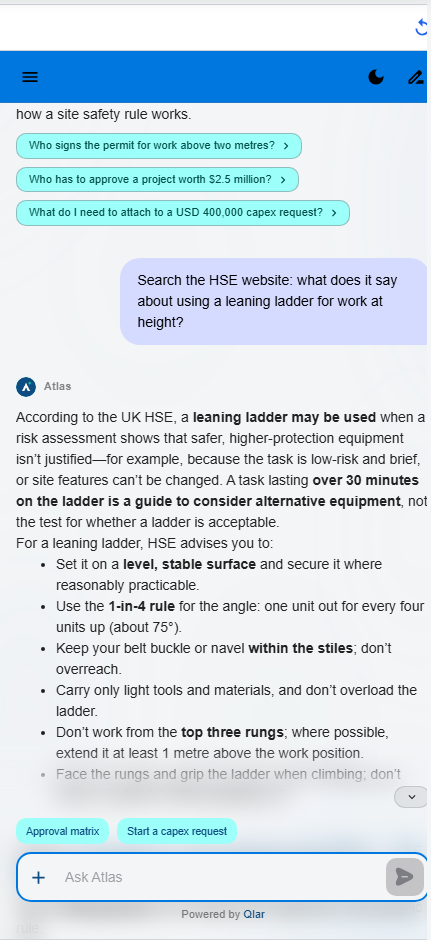
Ask a question that Kirana's SOPs do not answer and that is covered by the allowed domains:
Search the HSE website: what does it say about using a leaning ladder for work at height? -
Atlas answers from HSE guidance: a leaning ladder may be used when a risk assessment shows that safer, higher-protection equipment is not justified, for example for a low-risk, short task. It then lists HSE's advice, such as setting the ladder on a level, stable surface, using the 1-in-4 rule for the angle (one unit out for every four units up, about 75°), keeping your belt buckle within the stiles, and not working from the top three rungs.
-
Scroll down in the answer. Atlas names the HSE pages it used and makes clear that this is HSE guidance, not a Kirana SOP.
If the answer is not right:
- Atlas says it cannot find the information. Check that Enable Web Search is on and that you clicked Save. Then ask again in a fresh conversation.
- Atlas cites a site that is not on your list. Check the spelling of the domains in Allowed Domains (no
https://, no trailing slash). - Atlas answers from its knowledge base instead. That is expected when the knowledge base covers the question. Ask about something your documents do not contain, or start the question with "Search the HSE website".
When you are happy with the answers, click Publish so real users get the change. See Preview and Publish Changes.
Next steps
- Next in the journey: Connect Your API, to let Atlas check project status in Kirana's own systems.
- Using Plugins: extend your agent with ready-made plugins for common operations.
- Analytics and Logs: see how your agent uses web content in real conversations.